Asset Quality Scoring Frameworks for Non-Designer Output
Objective scoring transforms visual quality judgment from mystique into measurable criteria.
Somebody on the growth team just hit publish on a one-pager, and they are not entirely sure it looks right. The deck matches the template, the logo is in the corner where it is supposed to be, and the headline is big enough to read, probably. That small hesitation before the click is the actual subject of this piece: what happens when the people making visual assets at scale have no designer in the loop to catch the thing they cannot quite name. Volume used to be the hard part. What replaced it is a quality bottleneck, and it is quieter, because nobody notices it until a client asks why the fourth slide looks like it belongs to a different company.
The judgment call a trained designer makes without thinking, does this look right, has no equivalent checkpoint for the person who never went to design school. So the gap gets filled one of two ways. Or a designer gets looped in after the fact to fix what shipped, quietly reintroducing the exact dependency the team was trying to eliminate by letting non-designers produce assets. Neither option is sustainable at volume, and both point toward the same unresolved governance question: what can this team publish without a designer's sign-off, and who actually gets to decide that? Nobody wants to be the one who has to ask.
What makes quality judgment feel subjective (and why it does not have to be)
"I don't have an eye for this" treats visual judgment as a mysterious gift instead of a set of measurable properties, and it is worth taking apart. A published automated slide-quality pipeline broke expert visual judgment into seven concrete dimensions, whitespace, colorfulness, edge density, brightness contrast, text density, color harmony, and layout balance, and scored them well enough to correlate strongly with how actual humans rated visual quality. Trained eyes are not pulling an opinion out of thin air when they say a slide looks cluttered or unbalanced. They are reacting to edge density and layout balance, two things a camera can count.
The more striking result from that same research: the seven-metric scoring approach beat leading vision-language models at predicting human visual quality ratings. That is a strong signal that visual quality judgment is pattern recognition running on a small number of variables, not some ineffable taste reserved for people with design degrees, and those variables can be written down, taught, and checked by someone who has never opened a design tool in their life.
Separate research on data asset quality, a hybrid multi-criteria framework published by Xu and colleagues in Quality and Reliability Engineering International, adds a caveat: quality dimensions carry different weights depending on context. Each one earns its own threshold, because what sinks a slide deck is not necessarily what sinks a social post.
The four criteria that cover most of what goes wrong in non-designer output
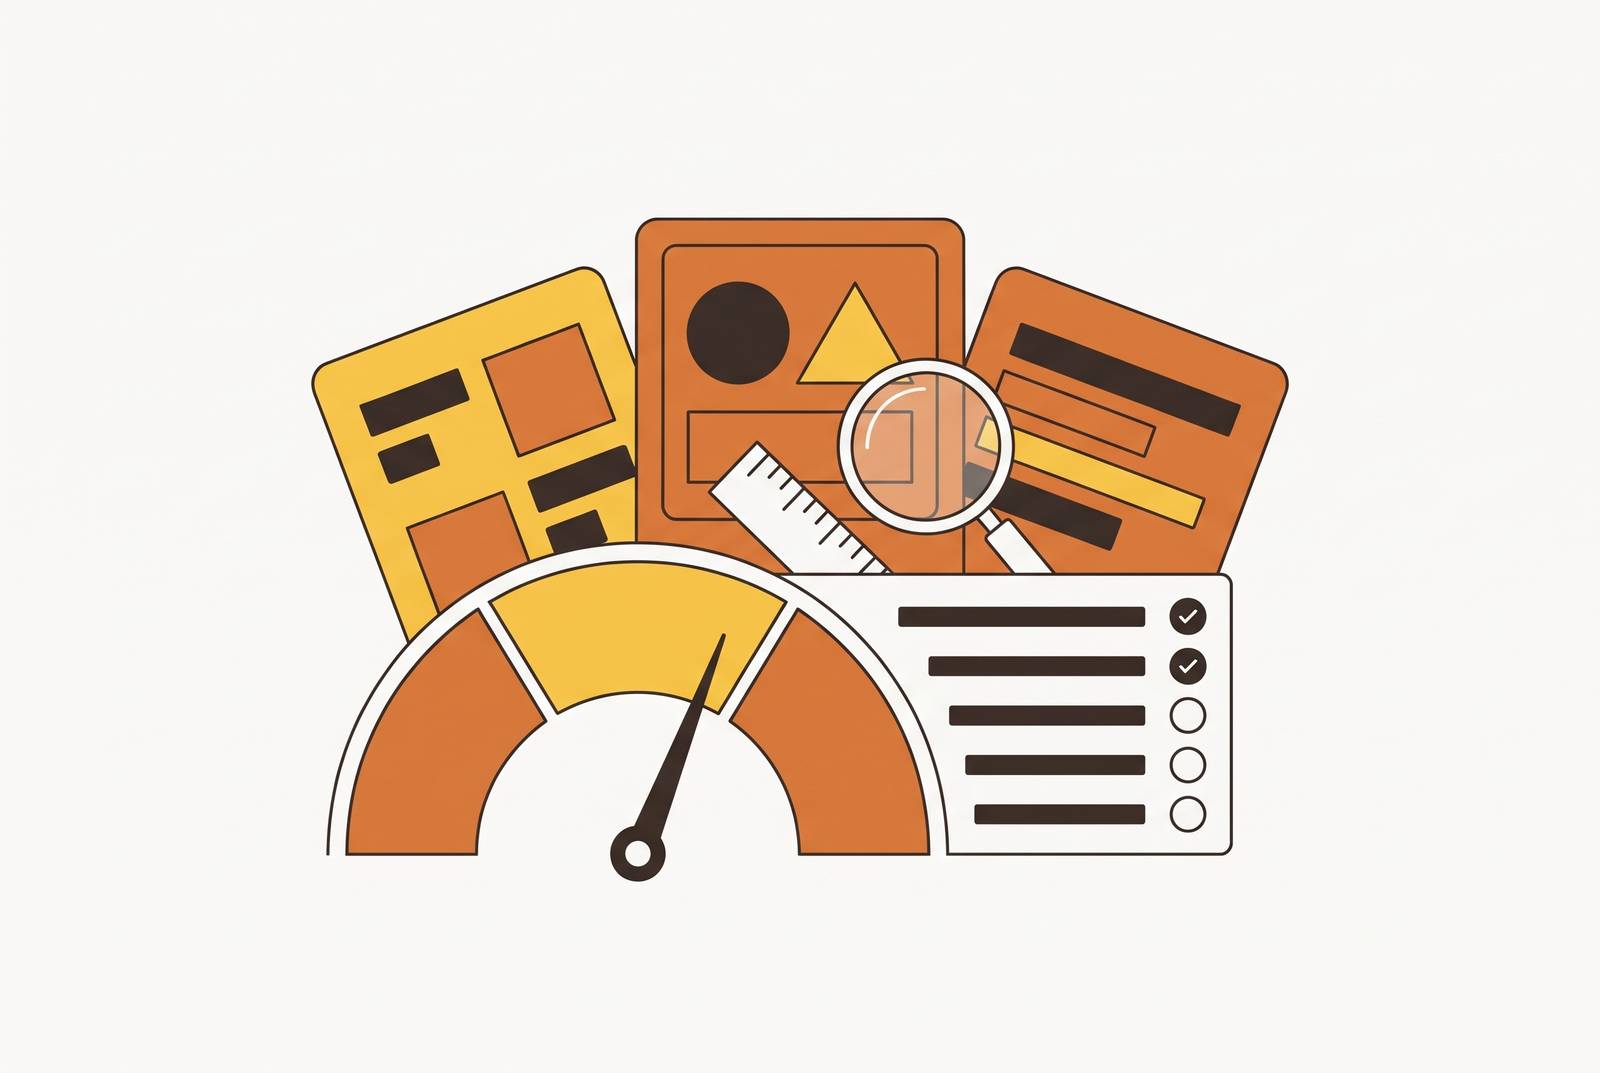
Four criteria cover most of what goes wrong when a non-designer builds an asset: brand consistency, visual hierarchy, legibility, and structural clarity. Each one converts into a question that takes about ten seconds to answer honestly, no design vocabulary required.
Brand consistency asks: does this match what the brand already looks like everywhere else? Check primary color usage, typography, logo placement, and image style against whatever the documented standard says those should be. Johns Hopkins University handled this problem at the source rather than the checkpoint, building template libraries with smart fields that auto-applied the correct logo, imagery, and typography for each school, removing the judgment call from production and leaving nothing to be caught later.
Visual hierarchy asks: can someone understand the main point within a few seconds of looking at this? Hierarchy comes from size contrast, weight, and placement, not from whether the layout happens to look pleasant. Edge density and layout balance, borrowed from the same seven-metric slide research, serve as decent stand-ins here even though they were not built to measure hierarchy directly: too many competing edges on a page is a reliable tell that nothing on it has been told to step back and let something else lead.
Legibility asks: can this actually be read, at the size and in the context where someone will actually encounter it? Brightness contrast, meaning text against its background, is the primary variable, and it happens to be one of the seven dimensions from that same slide-quality research. Test this by viewing the asset at its real display size, a social post on an actual phone screen, a slide projected or shrunk to a 13-inch laptop, not zoomed in on a design tool where everything looks fine.
Structural clarity asks: is the purpose of this asset obvious, and does every element on it serve that purpose? Whitespace is the signal to watch. Any chart or data point on the asset should carry a visible takeaway; if a viewer has to sit and derive the point themselves, the asset has failed at its one job. Broader content scoring frameworks treat CTA effectiveness as its own scorable dimension, and the same logic applies to visual assets generally: does this thing tell the person looking at it what to do or think next, or does it just sit there looking finished?
Turning the four criteria into a repeatable scoring routine
Four criteria are only useful if they get checked the same way every time. The real work is building a sequence, not memorizing a list. Score each criterion on a 1 to 5 scale, with the scale defined in advance of the review. What does a 3 look like for this particular brand? What does a 5 look like? Publish-ready, no caveats.
The checks run in a fixed order, and the order is not arbitrary. Brand consistency goes last. That sequencing exists for a practical reason. Catching a structural problem before spending time scoring brand consistency saves the team from polishing the color palette on an asset that needed to be rebuilt from scratch anyway.
Set a minimum threshold for each criterion individually, not a composite average across all four. A high brand consistency score should never be allowed to paper over a legibility failure, and that only works if each criterion has to clear its own bar independently. The final gate before anything publishes: the asset scores at or above threshold on all four, not on average across them. An asset that scores a 5, a 5, a 5, and a 2 does not pass just because the math looks generous.
None of this needs to feel heavy. The entire value of running the check is catching the one criterion that fails silently, the slide that matches brand perfectly but buries its point under six bullet points nobody will read. Track the scores by asset type, social post, one-pager, slide deck, email header, to reveal fairly quickly which category keeps failing the same criterion.
Why the framework needs template infrastructure
Scoring is a review mechanism. It catches a problem only after someone has already built the asset, making it a reactive check. Template infrastructure works earlier in the chain, and that difference matters enough to shape how a team should actually invest its time.
Locked templates, where logo placement, color blocks, and typography are fixed and only a handful of fields stay editable, remove brand consistency almost completely from the scoring burden. Those are not things a locked field can enforce, because they depend on what specific content someone chose to put into the template, not on the template's fixed properties.
A fair objection follows: if templates are already doing the work, scoring's role needs justifying. A non-designer can follow a template with total fidelity, logo correct, colors correct, fonts correct, and still produce an asset where the main point is buried under four competing headlines, the chart has no readable takeaway, or the whitespace has collapsed under the weight of someone's copy edits. Templates cannot catch that. Scoring exists specifically to catch what templates structurally cannot.
A handful of adoption metrics reveal whether this infrastructure is actually working, worth tracking over time: active users by team, template usage broken out by type, design requests over time (are teams still routing basic work to a designer out of habit, or has that stopped?), time from request to publish, and the rate of off-brand content incidents. If the scoring routine and the template infrastructure are both doing their jobs, off-brand incidents become rare enough that tracking them feels almost unnecessary, because the problem the metric measures has mostly been engineered out of the process.
Where human review must sit at volume
A scoring framework lets non-designers self-approve the routine stuff, the internal slide, the templated social post, without waiting on anyone. It cannot replace a human review gate for assets where getting something wrong actually costs the company. Those are two different problems, and conflating them is how teams end up either over-governing trivial work or under-governing the stuff that matters.
Every team using AI-assisted design tools eventually has to answer a governance question directly: what gets published without a designer or manager looking at it first, and who has the authority to approve something that failed a criterion anyway? Teams establishing governance for AI-assisted product work need to define, ahead of time, what requires human review before anything ships and what can move on its own. It is a structural requirement, because the alternative is figuring out the rule retroactively, after the asset that needed review has already gone out.
AI tools replace execution volume. They do not replace judgment, stakeholder navigation, or who gets blamed when a client complains, and a scoring framework for non-designer output is squarely an execution-layer quality check, not a stand-in for strategic review. The practical artifact that resolves most of this tension is a one-page decision tree mapping asset type to review requirement. Anyone on the team should be able to look at that one page and know which path applies without pinging a manager to ask.
Editable Design Infrastructure Sustains the Framework
Here is the quiet failure mode that kills a scoring framework after it looks like it is working: an asset fails a criterion, say legibility, and there is no way to fix it without starting over. If the output is a static, locked image, a scorer who spots a brightness contrast problem cannot do anything productive with that information. The only path forward is a brand-new generation request, turning the scoring step into busywork.
The fix sits in the asset format, not the scoring logic. The score turns into an action. That is the actual line between a design platform that outputs editable, structured files and a tool that generates a static AI image: the static version gives a result worth evaluating, not one worth repairing, and repairing beats regenerating almost every time, because regenerating throws away everything that was already correct about the first attempt.
The same logic applies outside of pure visual design, too. A 60 percent time savings on a web page that then cannot be touched without a developer is not actually a win, it just moves the bottleneck from the build phase to the revision phase. Editable output lets someone respond to a failed legibility or hierarchy score by actually adjusting the page.
Brand consistency becomes close to automatic once brand tokens, meaning colors, fonts, and spacing values, live inside the platform itself rather than getting applied by hand on every single asset. At that point the template infrastructure from the earlier section and the scoring framework from this one stop being two separate workflows running in parallel. They become one system: templates prevent the errors that are cheap to prevent structurally, and scoring catches the small number of judgment calls that no template was ever going to make for anyone.